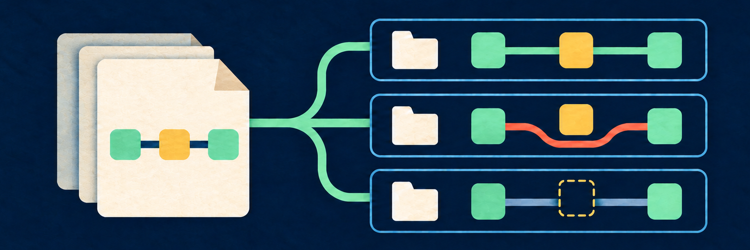
Zero-day readiness: fast response starts before disclosure
Table of Contents
When the next critical vulnerability becomes public, leadership should be able to establish exposure across the organization, put the response into developers’ workflows, and track every affected system through to verified remediation. If no usable patch exists, that same visibility should support containment. The target is a response that reaches the entire relevant estate without waiting for every team to assemble its own answer.
Teams can patch everything they found and still be unsure whether they looked everywhere. The organization may assume it is “99% patched,” without knowing how much of its software estate the response actually covered. A forgotten build runner with production credentials or an acquired company’s infrastructure may never have entered the campaign, leaving exposure that no progress report accounts for.
Getting there requires preparation before disclosure. I call that standing engineering responsibility zero-day readiness: keeping the estate discoverable, its evidence queryable, and its systems ready to change. It is Step 0 of the response process. The same capabilities support urgent response to other critical disclosures. The ideal response makes clear why those capabilities have to be maintained in advance.
TL;DR
- Aim to assess exposure, activate developer-facing guardrails, and establish reliable progress reporting in less than a day. Track remediation through to verified fixes in running systems.
- Step 0 makes that possible: a complete, continuously maintained software catalog, queryable evidence, and continuously enforced DevSecOps standards. Fund and improve these capabilities before the next incident.
- Apply controls according to production access, data sensitivity, and compliance scope. Include internal systems and CI/CD that can affect production, across every deployment path.
- Keep every service owned and ready to update, even without a dedicated team. The difficult remainder should shrink over time; accepted risks should already be known and documented.
AI makes the preparation harder to postpone
More than a third of all CVEs were published in the last two years alone. Almost a quarter this year alone, and it is only November.
Monthly vulnerability disclosures more than doubled in seven months. Google Threat Intelligence Group counted 5,045 in January 2026 and 10,740 in August.
Daniel Stenberg, curl’s founder and lead maintainer, described the change in reports reaching his project:
Our current challenge is much harder: high volume, high quality.
As vulnerability discovery becomes easier to scale, defenders have to absorb more legitimate repair work. AI can help investigate findings and produce patches. Every downstream organization still has to identify its affected installations, validate changes, and finish the rollout.
Reconstructing that information during each emergency makes response time depend on how quickly teams answer questions. The same missing inventory, undocumented runner, or unmaintained service can delay incident after incident. Those are recurring engineering investments leadership can choose to make before the next disclosure.
The ideal zero-day response
But let’s pause for a second and imagine the perfect zero-day response. Imagine the next critical vulnerability lands tomorrow. In an ideally prepared organization, what would you expect to know by the end of the day? How would the response reach every affected system, and what would let you declare it complete?
I would aim to establish exposure, activate targeted guardrails, and produce trustworthy progress reporting in less than a day. Full remediation may take longer.
Containment runs in parallel throughout. Security can use exposure evidence, CISA’s known-exploited catalog, and SSVC to prioritize action. An actively exploited path may need isolation before the organization has finished assessing every system.
Here’s what this might look like.
Step 1. Establish exposure from maintained evidence
There is a pre-existing fully cataloged software inventory, rich in SDLC metadata.
The incident team queries the estate for affected implementations and configurations, their production relationships, and accountable owners. It can distinguish confirmed exposure from systems that need further assessment. Where the advisory requires a new fact, a targeted collector extends the existing dataset across ecosystems.
If this begins with a company-wide survey or an AI-guided investigation assembled from scratch, the organization is spending its response window on unfinished Step 0 work. Surveys can settle exceptions; they cannot establish that every relevant corner has been reached.
Step 2. Put the response into the developer’s workflow
The incident requirement becomes an applicable, actionable guardrail with a deadline. Developers encounter it where they can fix their services:
- Pull requests identify the exposure and required action. Warnings become blockers after a risk-appropriate grace period; an actively exploited critical issue may require immediate enforcement.
- Deployment controls prevent vulnerable releases and enforce containment policy against the actual artifact and destination, including nonstandard deployment paths.
- AI coding tools receive the same findings during their edit-and-test loop, so proposed fixes account for the requirement before review. Independent checks still enforce it if the agent ignores the feedback.
This distributes remediation to the engineers who know each service’s compatibility constraints and rollout risks. Central teams provide corrected base images and migration support. A mass announcement or Jira campaign can support that work, but neither ensures action before the deadline.
After the deadline, risk-based restrictions can block unrelated changes to an affected service. Containment and remediation must remain possible, with audited, expiring emergency bypasses. Agree in advance who can authorize a bypass when restoring availability conflicts with the exposure policy. Dormant services need scheduled assessment and escalation because no new PR will trigger their response.
For example, suppose a critical advisory affects a bundled runtime only when a particular feature is enabled. The artifact inventory identifies candidate images; deployment and runtime evidence map them to running instances and owners. Instances without current configuration evidence remain unknown. A targeted collector checks the feature, recording the evidence timestamp and advisory revision so the team can reassess its conclusions if guidance changes.
If no patch is available, owners disable the feature where supported or isolate potentially affected instances according to risk. Deployment controls prevent new exposure while allowing the containment change. When a fixed image is ready, current runtime evidence must show that it is running across the affected installations before they count as remediated.
Step 3. Run one organization-wide remediation view
Leadership sees the required controls across the in-scope estate, whether each control has current evidence, and which teams remain exposed or overdue. This view reconciles all required scanners and other evidence sources. Each scanner’s coverage is checked against the inventory, so a missing scan cannot silently shrink the reported scope.
Keep unknown, affected, mitigated, fix-in-progress, and verified-remediated states distinct. Show accepted risks separately, with an approver and expiry. Retain the original remediation deadline so a new scan or replacement ticket cannot reset the SLA clock.
Dan Lorenc, Chainguard’s co-founder and CEO, captures the completion problem:
A fix in a release still isn’t a fix in production
The reporting must preserve that distinction until the corrected implementation is active across the affected installations, including internal services and CI/CD.
Step 4. Intervene in the difficult remainder
Enforcing organization-wide standards for ownership, testing, and deployment should steadily shrink this remainder toward zero. Services that fall below those standards get remediation work before the next emergency.
Dependabot, Renovate, and AI-generated PRs can accelerate fixes. AI is particularly useful when an upgrade needs compatibility changes or focused tests. Review and rollout verification still matter: Trail of Bits found 21 confirmed regressions in a review of more than 130 merged, engineer-authored PRs from AI-assisted patching work. None broke security protections, but the changes still required correction.
Leadership directs help through established ownership and escalation paths. A service without a dedicated team still has a named owner with the access, authority, and capacity to intervene during a critical incident. Known operational gaps and accepted risks are recorded in advance, with an approver, an expiry date, and a response plan. The new advisory prompts a review of those decisions; it should not be the moment anyone discovers that a service has no owner or cannot be safely updated.
Step 5. Verify completion and prevent reintroduction
Closure requires evidence from the affected running systems, including replicas and relevant environments. The same requirement must also cover future provisioning and rollback paths, so an old image cannot quietly restore the exposure. Suspected compromise triggers a separate investigation and recovery track, including checks for persistence and exposed credentials. A verified patch does not close that investigation.
A “fully patched” report should mean verified remediation across the identified in-scope installations for this incident. Unknowns and accepted risks remain separate, unresolved items. The guardrail and discovery continue after the campaign closes; completion is no claim of immunity from undiscovered vulnerabilities.
What makes that response possible
That response works because the incident team can use capabilities the organization already operates. The first query runs against a complete catalog with current evidence. A new guardrail reaches developers through enforcement points already connected to their workflows. Service owners have a tested path for deploying the fix. High DevOps maturity is enforced throughout the SDLC process.
If teams still have to build those capabilities, that work becomes part of the emergency. A patch can be ready while the organization is still finding affected systems or figuring out how to update them. To make the ideal response possible, leadership has to invest in that preparation ahead of time and keep it working as the estate changes. That is Step 0: zero-day readiness.
The preparation has to reach the organization you actually operate. A well-instrumented platform covering most new services leaves a response problem wherever older services, acquisitions, or unusual deployment paths fall outside it. The standard should be that every relevant system is covered by its required controls, or appears as an explicit gap with an owner.
Zero-day readiness
Know the estate and what can affect production
Without continuous discovery, leadership cannot establish the scope of a response. Manual registration is useful for business context, but it cannot establish completeness. A running workload without a known repo, or an active runner outside the approved fleet, should create work before an incident forces someone to find it.
IDP catalogs such as Backstage can provide ownership and business context. Establish coverage independently, then make the catalog data trustworthy enough to drive enforcement:
- Discover every repo across every source-control organization, whether registered or not. Reconcile against cloud, runtime, artifact-registry, and CI/CD inventories, and verify that collection reaches every intended account and environment.
- Validate metadata before using it to scope controls: active owners, consistent classifications, and unique service identities. Distinguish individual services within monorepos and track shared-code dependencies so changes trigger checks for every affected service.
- Put missing or incorrect catalog data in front of service owners through PR feedback. Start with warnings, then require valid entries, so teams clean up their own data and new omissions cannot accumulate.
- Enrich declarations with observed behavior. A service labeled “experimental” that deploys to production needs its classification corrected. Refresh on changes and reconcile periodically so ownership and risk classifications stay current.
Context determines which controls apply. A payment service, an isolated experiment, and an internal release tool have different requirements. Production access, sensitive data, compliance scope, and ownership belong in the inventory. So do the relationships through which a system can affect production: building artifacts, publishing images, signing releases, or controlling deployments.
An internal tool that can publish a production image belongs in the production security boundary. An unclassified system needs an owner to resolve its status; missing metadata must not quietly exempt it from controls. Context-aware enforcement both catches that exposure and avoids imposing payment-service requirements on a disconnected prototype.
Have the evidence ready to query
Without maintained evidence, the first day of response becomes a data-gathering exercise. The goal is an organization-wide answer one query away: known affected systems, owners, sensitive environments, and what still needs investigation. Executives should be able to ask which teams remain exposed and get a defensible answer without commissioning a new reporting project.
Software bills of materials (SBOMs) must be generated for shipped artifacts, linked to their exact identity, and queryable centrally. Coverage has to include legacy services. Where a service cannot yet produce an SBOM, deployed-package evidence can provide interim visibility, with the remaining gap explicitly owned.
Require lock files where the ecosystem supports them, and record resolved dependencies. The inventory must also cover language runtimes declared in configuration, actual runtime versions, CI tools, plugins, downloaded binaries, native libraries, and runner images. A dependency inventory cannot answer every kernel or trust-store incident.
Some facts exist only while a CI/CD job runs. Collect the tools and versions actually used, resolved dependencies, image identities, and scanner results at that point. Preserve their relationship to the source revision and artifact. Different ecosystems and pipeline conventions need to produce comparable, queryable software development lifecycle (SDLC) evidence without forcing every team onto the same stack. Reusing existing scan results also avoids adding another expensive scan to every build.
A new advisory will sometimes require new evidence. The collection infrastructure should already support deploying a targeted collector across the estate and reporting where it succeeded or failed. AI can help write that collector. It cannot establish completeness by searching an arbitrary subset of repos, or recover transient build evidence that was never retained.
This infrastructure needs an operational budget. GitHub’s API guidance and GitLab’s rate limits make an emergency organization-wide crawl a poor dependency for incident response. Continuous collection, shared caching, and rate-aware scheduling should keep incident queries independent of fresh source-control crawls and protect capacity for developer work. Missing or stale data must remain visible even when a provider is unavailable.
Keep the estate changeable
Knowing where a vulnerability exists does not give the organization the ability to remove it. Without maintained rollout paths, the remediation deadline is constrained by the service that can no longer be rebuilt, tested, or deployed safely.
Put VMs, container base images, and runner images on a maintained golden-image program. Require pinned versions or immutable digests, automated refreshes, and evidence that old instances have been replaced. Pinning without an update process preserves vulnerable versions. Give one platform team accountability for the runner fleet, including exceptions, with authority to replace affected workers and limit their access to production.
Every deployment path needs an owner and an enforceable control point, including manual and emergency paths. Production resources should be traceable to their source repo, commit, build, and artifact. Tags help navigation; deployment records and provenance establish whether the claimed artifact is actually what shipped.
These practices turn a runtime or kernel upgrade into an existing rollout operation. Without them, each incident can require a separate migration project for the systems that never adopted the standard path. Supporting diverse deployment mechanisms is reasonable. Leaving some of them outside the response process is an unresolved risk.
Be able to enforce the response
A remediation SLA is credible only if the organization can detect a violation, reach the responsible team, and enforce the deadline. That capability needs to exist before a critical incident requires its use.
Establish how applicable requirements reach developers in pull requests, AI-assisted coding workflows, and deployment controls. Required checks, organization-level repository rulesets, and policy engines can supply parts of this system. Test their reach across the estate, their handling of missing evidence, and the emergency bypass process. A documented standard adopted by some teams gives leadership only partial enforcement.
A collection failure must not silently clear a known exposure or count as a pass. Define evidence freshness limits and risk-based behavior for outages in advance, including which deployments require fresh evidence or an authorized exception. Validate new checks against known affected and unaffected cases before broad blocking, and exercise the emergency path with a broken or unavailable check.
Coverage also includes the evidence producers. If a service requires dependency, container, and host scanning, the organization needs to know whether all three happened successfully and recently enough. A clean result from one scanner cannot stand in for two missing scans. Store the source, scope, and freshness of the evidence used to make each decision.
Security should define risk-based CVE deadlines and exception requirements. Platform engineering should operate collection and enforcement. Engineering leadership must give service owners the capacity and authority to meet those deadlines. Exceptions need named approvers and expiry dates; accepted risk remains visible as exposure.
Own and improve DevSecOps maturity
DevSecOps maturity needs an accountable owner and a funded improvement program across the organization. Establish and enforce minimum standards for testing, deployment, recovery, and security controls. Address gaps between incidents, and use readiness drills to verify that the estate is becoming easier to update safely.
Every service needs an accountable owner, even if it no longer has a dedicated team. Ownership must survive reorganizations and the end of active feature development, with access and operational knowledge handed over. Gaps in testing or deployment need funded remediation, or an explicit decision to isolate or retire the service. These decisions belong in planning, before an incident forces them.
An organization can patch its maintained services quickly and still spend weeks on the difficult remainder. AI-generated PRs reduce some implementation work. They do not supply an accountable owner or establish that an untested service can tolerate an upgrade.
Reserve remediation capacity, maintain test and rollback paths for critical services, and pre-authorize containment when a safe fix is unavailable. Least privilege and segmentation reduce what exposed systems can reach while remediation proceeds. None of this requires buying a particular product, and none can be delegated entirely to the incident-response team.
Recent incidents show why these dependencies matter
The recent advisories cross ownership and inventory boundaries in ways that make preparation consequential. Several involve documented AI-assisted discovery; others illustrate the downstream workload without established AI discovery. They also differ in exploitation status. The argument for readiness does not depend on treating every disclosure as an exploited zero-day.
| Recent example | Organizational response dependency |
|---|---|
| Linux MPTCP / Go, Copy Fail, and Xen XSA-523 | Application exposure and host ownership can be separate. Go’s MPTCP default helped expose a kernel dependency; Copy Fail also matters on CI hosts; Xen requires action at the hypervisor. Completion depends on coordinated host rollouts and active-version evidence, beyond application or guest rebuilds. |
| Node / Brotli and PHP2Shell | Runtime copies can sit outside package-manager inventories, including custom images and embedded installations. The response needs runtime coverage and redeployment of their consumers. An application dependency campaign alone has the wrong scope. |
| SSHole and Python’s FIPS-enforcement regression | Applicability depends on operating conditions. SSHole involves a particular OpenSSH/musl/non-PAM and authentication/account combination. Python 3.14.10’s regression affects hashlib when OpenSSL runs in FIPS mode. Version lists need configuration context, and security-sensitive configurations need upgrade testing. |
| GitLab / Ruby / Onigmo | Developer infrastructure needs the same accountable rollout as customer-facing systems. The upstream Ruby fix preceded fixed stable releases by months. An upstream repair and a deployed vendor fix are separate milestones. |
| eMudhra / emSign weak intermediate keys | Trust-store changes have to reach browsers, CLIs, containers, and embedded clients, accounting for cross-signed paths. Readiness requires an inventory of trust dependencies beyond application SBOMs and a way to validate the resulting client behavior. |
| PostgreSQL’s August security release | Server upgrades alone do not cover client and backup tooling. Some fixes also require configuration changes or re-encryption of affected stored values. Completion criteria must include operational and data-repair work across owners. |
| Plex2Shell on NAS appliances | Appliance-hosted applications need ownership and discovery too. QNAP advises treating vulnerable internet-exposed installations as potentially compromised. The response can require recovery and credential resets, beyond updating the application. |
The executive dependency is consistent across these cases: application teams, platform owners, infrastructure teams, and security need to act on the same affected population and completion criteria. That coordination is much faster when the relationships and rollout mechanisms already exist.
Make readiness an investment with a testable return
Every incident otherwise repeats some of the same costs: finding systems, collecting evidence, chasing owners, and recovering neglected deployment processes. Maintaining those capabilities lets subsequent responses start further along. It also allows more precise intervention, with urgent controls aimed at affected services and production-critical infrastructure instead of indiscriminate disruption across engineering.
The risk reduction comes from shortening the time affected systems remain exposed and reducing the chance that an unobserved system escapes the campaign. Its value depends on which systems and access paths are involved; an aggregate patch percentage cannot express it. AI can reduce patch-authoring effort, but validation and rollout still determine the cost of a completed fix.
Compare the recurring cost of discovery, evidence collection, and enforcement with the response effort saved across incidents and routine upgrades. Track exposure duration for high-impact systems separately from that labor saving.
Give Step 0 a funded backlog and named owners across engineering, platform, and security. Start with production and the systems able to change it, then reconcile outward until every part of the estate has an explicit classification and control policy. Legacy services and unusual deployment paths need milestones too, rather than permanent exclusion from the target.
Then run a readiness drill with a vulnerability that crosses an application and infrastructure boundary. Include a legacy service and a nonstandard deployment path. Measure:
- Time to establish the exposed and unknown population, checked against independent discovery.
- Time to put the requirement into effect across applicable development and deployment workflows.
- Time to verified remediation, including the last difficult service, with mitigations and exceptions reported separately.
- Engineering effort spent reconstructing evidence and chasing ownership instead of validating and deploying fixes.
A tabletop discussion is not enough to establish those results. Exercise the collection and enforcement paths, and rehearse a safe rollout on representative systems. Use the failures to decide where the next investment goes. A sizeable engineering organization should be able to demonstrate its zero-day readiness before an incident makes the demonstration mandatory.
Where Earthly Lunar fits
We build Earthly Lunar to help with Step 0: collecting structured posture evidence from repos and CI/CD, making it queryable, and applying guardrails in developer and AI-agent workflows, on PRs, and at deployment gates. Lunar makes zero-day readiness possible at organizational scale. That foundation can shorten the work between a new incident requirement and organization-wide assessment and enforcement.
It complements existing scanners, patch tooling, and incident response. Ownership, safe rollout, and verification still need investment. Whether you assemble the infrastructure yourself or use a product, test readiness against the service your current process is most likely to leave behind.